In this post, we’ll go over Hadley Wickham’s three principles for ensuring tidy data.
Each variable has its own column
At first glance, data management sounds boring. When students think of statistics, they think of tests, formulas, and results. What they rarely expect is that they’ll spend most of their time simply getting the data into a form that can be analyzed.
Hadley Wickham, one of the most influential statisticians and software developers of our time, noted in a widely cited paper what practitioners have long known: About 80% of the time spent on data analysis goes toward cleaning and preparing the data. Not on the analysis itself. Not on the interpretation. On the cleanup.
The paper offers a clear proposal for what clean data should look like—“Tidy Data”—and it follows three principles. The first: Each variable has its own column.
That sounds obvious. But it isn’t.
Take a look at a typical dataset that records income data by religious affiliation. The rows are religions, and the columns are income groups: under 10,000 euros, 10,000–20,000, and so on. Visually, this looks neat. Statistically, it’s a problem. The income groups aren’t column names—they’re values. They don’t belong in the header, but in a separate column called “Income.” As long as that isn’t the case, no statistical software in the world can work with it properly.
This is Pattern Number One in Wickham’s catalog of typical data chaos problems: column names are values, not variables. And it’s the most common problem of all—because it almost always arises for the same reason. The table was built for presentation, not for analysis. It looks good when you look at it. But it fails as soon as you import it into software.
The second pattern is even more subtle: multiple variables are packed into a single column. The WHO tuberculosis dataset is a good example. It contains columns like “m1524”—which stands for male, aged 15 to 24. Two variables, one column name. Readable by humans, unusable by software. Before you can work with it, you have to separate them: one column for gender, one for age group.
What these two patterns have in common is that they both violate the same principle: one variable, one column. As soon as this principle is broken—whether because values are disguised as column names or because multiple variables have been crammed together—the analysis breaks down. You’ll either get error messages or, even worse, results that are incorrect without you realizing it right away.
Or as I always say: Running tests is rarely a problem. The critical challenges almost always lie in data management. And they almost always start with the columns.
Each observation has its own line
While the first principle of Tidy Data concerns columns, the second concerns rows. And it is violated just as often—for equally understandable reasons.
The principle is: Each observation has its own row.
An observation is simply what was measured for a given unit at a specific point in time. If you survey a person on ten different days, you have ten observations—not one person with ten columns. If a song was on the charts for ten weeks, it has ten chart positions—not one row with ten columns.
But that is precisely the classic problem in the Billboard dataset that Wickham analyzes as an example. Each song has its own row there. The chart positions for Week 1, Week 2, Week 3—through Week 75—are listed in separate columns: wk1, wk2, wk3, and so on. This is convenient for data entry; it saves space. Each song appears only once. But statistically, this is a problem because each week is a separate observation and therefore requires its own row.
Why is this so important? Because statistical software works with rows, not columns. If you want to know how the average chart position changes over the weeks, you need a “Week” column and a “Position” column—and one row per song per week. You won’t get very far with the original format.
The corresponding chaos pattern is the most complicated of all: variables are found in both rows and columns. Wickham illustrates this with a weather dataset. Maximum and minimum temperatures—which are actually two variables, meaning two columns—aren’t listed side by side, but one below the other. “tmax” and “tmin” are values in a column called “element,” while the actual temperature figures are in a different column. What should be one row per day ends up being two rows—one for tmax and one for tmin.
To clean this up, you need to take two steps in opposite directions: first, split the data, then merge it back together. The result is one row per day, each with a column for the maximum and minimum temperatures. Neat—and easy to analyze.
What both cases show is that the problem doesn’t stem from carelessness, but from a conflict of objectives. Data is almost always collected and stored for a specific purpose—for data entry, for presentation, or for compact storage. This purpose is rarely “statistical analysis.” The result is structures that look good but fail when analyzed.
Recognizing this is the first step. The question “Is this one observation or several?” is simple—but it’s asked surprisingly rarely.
Each type of observation has its own table
The third principle of Tidy Data is the most abstract—and the most frequently misunderstood. It’s not about columns, nor about rows, but rather about the question: What actually belongs together?
The principle is: Each type of observation unit has its own table.
What is an observation unit? A song. A person. A measurement day. A school. An observation unit is the “thing” about which you collect information. And the problem arises when you put information about different things into the same table.
Take the Billboard example again. The dataset contains two types of information: facts about songs—title, artist, length—and facts about their weekly chart positions. These are two different units of observation: the song as such, and the song in a specific week. If you mix these in a single table, the title, artist, and length are repeated for every week the song was on the charts. This is inefficient. Worse still: it can lead to inconsistencies. If the artist is corrected in one place but not in another, you suddenly end up with conflicting data.
The solution is normalization: two linked tables. One for songs, one for chart positions. Linked via a common ID. Each piece of information exists only once, in exactly one place.
The opposite of this is the fifth and final chaos pattern in Wickham’s catalog: an observation unit is spread across multiple tables. Annual data stored in a separate file for each year. Each file is organized on its own, but together they’re nearly impossible to analyze—especially if the files have slightly different structures, different variable names, or different conventions for missing values.
Too much in a single table, or too little—both violate the same principle. The question is always the same: What exactly is the unit here that I want to make a statement about? If the answer encompasses two different things, you need two tables. If the answer is spread across multiple files, you have to merge them.
That sounds like database design—and it is. Wickham explicitly refers to Codd’s relational algebra as the foundation. The only difference is the language: What database developers know as the “third normal form,” Wickham translates into statistical terms that are more accessible to researchers.
And that is the true value of the tidy data principles as a whole. It’s not that they’re new—the ideas behind them are decades old. Rather, they establish a standard that applies to everyone: to R users just as much as to SPSS users, to experienced data analysts just as much as to students working on their first thesis. Anyone familiar with the three principles can tell at a glance when something is wrong—and knows how to fix it.
A Summary of the Three Principles
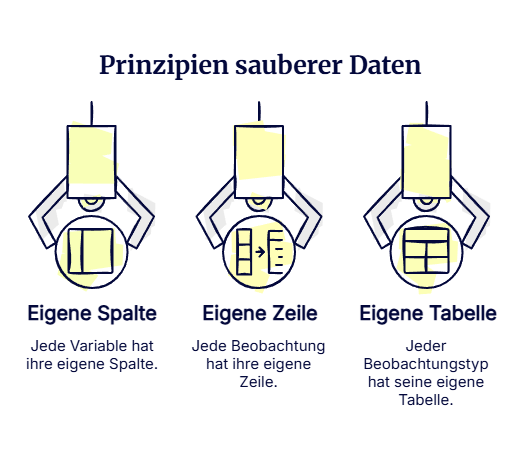
Clean data follows three principles: Each variable has its own column, each observation has its own row, and each type of observation has its own table. These rules sound simple—but they’re constantly violated in practice because data is almost always organized for presentation or data entry, not for analysis. Those who have internalized these three principles not only avoid error messages and incorrect results but also spare themselves that frustrating moment when they realize: The problem wasn’t with the statistics, but with the dataset.