
Measures of dispersion in descriptive statistics
Variance and Standard Deviation
In descriptive statistics, variance and standard deviation are two of the central measures of dispersion, often used together with the arithmetic mean to describe the distribution of data. They measure how much the individual observations vary around their mean.
The variance of a sample is defined as the arithmetic mean of the squared deviations of each observation from the mean:
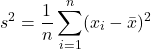
Here, n is the number of observations, x_i is the value of the i-th observation, and x̄ is the arithmetic mean. Squaring the deviations ensures that all deviations are positive, since negative and positive deviations would otherwise cancel each other out.
The standard deviation is the square root of the variance and therefore has the same unit as the observations themselves:

The standard deviation is easier to interpret because, unlike the variance, it is not expressed in squared units. It is particularly useful for specifying intervals that contain certain proportions of the data, provided that the distribution is approximately normal.
Worked Example by Hand
Let’s assume that we have the following data series with n = 5 observations:
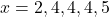
- Calculating the mean:
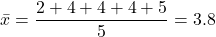
- Calculating the deviations and their squares:
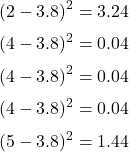
- Calculating the variance:
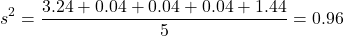
- Calculating the standard deviation:
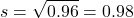
Here’s another example in the video:
Calculation in Excel/Sheets
You can find the calculation in Excel/Sheets here:
Calculation in R
In R you can calculate variance and standard deviation using the following functions:
x <- c(2, 4, 4, 4, 5)
var(x)  # Variance
sd(x)   # Standard Deviation
In this case, both calculations would produce the following results:
var(x)
# [1] 0.96

sd(x)
# [1] 0.9797959
Calculation in SPSS Statistics
To calculate variance and standard deviation in SPSS Statistics, follow these steps:
- Open SPSS and import your data.
- Under “Analyze,” select “Descriptive Statistics” and then “Descriptives.”
- Select the variables for which you want to calculate variance and standard deviation.
- Click “Options” and make sure that “Standard Deviation” is selected.
- Click “OK” to display the results.
The coefficient of variation
Another useful measure of dispersion is the coefficient of variation (CV). It is defined as the ratio of the standard deviation to the mean:

The coefficient of variation is dimensionless and allows you to compare the dispersion of data sets with different units or means.
Quantiles
Quantiles are measures of dispersion that divide a distribution into equal parts. They describe specific points in the distribution of the data at which a certain proportion of observations is less than or equal to that value. A well-known example is the median (the 50th percentile), which divides the data into two halves. Other important quantiles are the first quartile (Q1), which describes the lower 25% of the data, and the third quartile (Q3), which describes the upper 25%.
Box Plot and Interquartile Range
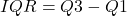
Another measure of dispersion is the interquartile range (IQR), which describes the range of the middle 50% of the data. It is calculated as the difference between the upper (Q3) and lower quartile (Q1):
The interquartile range is resistant to outliers and provides a robust impression of the dispersion of the data. It is often used together with the box plot to visualize the distribution. The box plot uses five values that summarize the distribution of a data set very effectively:
- Q1 (as the beginning of the box)
- Q3 (as the end of the box)
- IQR = d_Q (as the length of the box)
- Q2 = Median (as the line in the box)
- x_min and x_max as the ends of the whiskers
Please note: There is no single standard box plot—the parameters that define a box plot can vary! For example, the ends do not always have to be specified by the minimum and maximum values!
Example of a Box Plot in R
To create a box plot that shows the interquartile range, you can use the boxplot() function in R:
boxplot(x, main="Boxplot of the data series", ylab="Values")This generates a simple box plot representing the middle 50% of the data.
Conclusion
Measures of dispersion such as variance, standard deviation, and interquartile range provide us with important information about the distribution and variability of data. In descriptive statistics, they are indispensable for understanding the behavior and characteristics of a sample.