
Causality
Causality is one of the most fundamental concepts in science: It describes how causes lead to effects. For example, when you throw a stone into water, it causes the resulting waves. In statistics, causality plays a special role because we often examine relationships between variables to find out whether and how a change in one variable affects another.
What exactly is causality?
Imagine you want to find out whether something has a particular effect. For example: Does studying for an exam really lead to better grades? This involves the idea of causality—in other words, the question: Did one thing (studying) actually cause the other (good grades)?
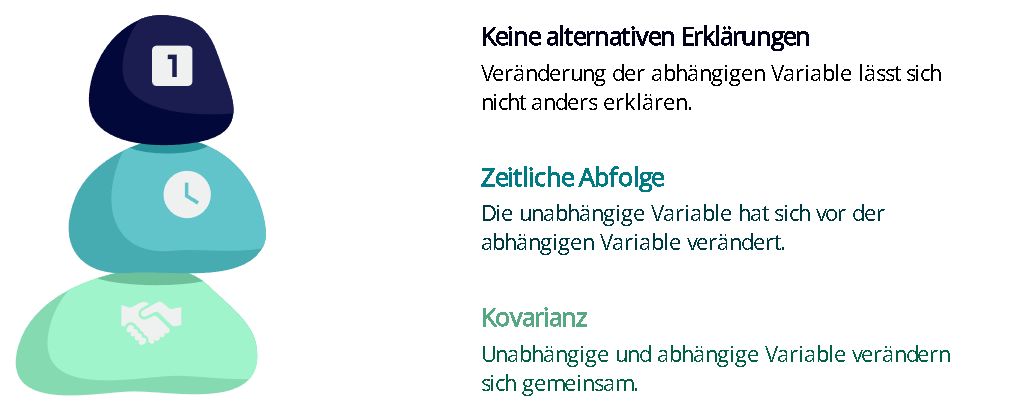
We use three characteristics to determine causality:
- Covariance: If you study more (the cause), you must be able to see that your grades (the effect) improve. There must be a relationship.
- Temporal sequence: The studying must happen before the better grade; otherwise, it cannot be the cause.
- No alternative explanations: Perhaps you got better grades not because you studied, but because someone helped you. To be sure that studying is the cause, we must rule out all other possibilities.
Sounds quite simple, doesn’t it? But unfortunately, in actual research practice, it is much harder to directly prove these three simple characteristics. In research—for example, in psychology—there are many things we cannot control. Perhaps the person had a good night’s sleep or was simply more motivated. It is impossible to rule out all other causes. That is why, in the social sciences, causality can often only be suspected, but rarely proven with 100% certainty. However, statistics can help us clarify at least the first point.
Correlation vs. Causality
It is important to understand the difference between correlation and causality. Correlation means that two variables are related—for example, ice cream sales and the number of sunburn cases both increase in summer. However, this does not mean that ice cream sales cause sunburn (causality). In statistics, we therefore need to be careful not to mistakenly interpret correlations as causality.
This relates to the second and third criteria mentioned above. Just because a covariance (or its standardized version, the correlation) exists does not mean that the correct temporal order is present or that there is no alternative explanation.
How do we identify causality in research?
Recognizing causality can therefore be very difficult. You can get a good sense of this difficulty from the following thought experiment: A switch is connected to a device. When you press the switch, the device makes a sound. Here, it is easy to see that all the characteristics of causality are present. But now let’s manipulate the connection between the switch and the device so that it does not always work. Sometimes the device might even do something completely different—for example, a light on the device might turn on. None of the prerequisites for our three criteria has changed. But it has become much more difficult to see the causality.
The best tool we have in research for demonstrating causality is the experiment. In an experiment, I can clearly determine what came first (criterion 2), because I deliberately manipulate one variable (the independent variable) and measure how another variable (the dependent variable) changes. I can largely rule out alternative explanations through the controlled nature of the experiment (criterion 3). Covariance (criterion 1) remains a matter of subsequent statistical analysis.
Example: Imagine you want to know whether caffeine improves concentration. You can divide a group of students into two groups. One group receives caffeinated coffee, while the other does not. You then test their ability to concentrate. If the group receiving caffeine performs better, this could indicate a causal relationship between caffeine and concentration. Of course, there are also other factors that affect concentration, but in a laboratory setting I can largely rule them out (and with a sufficiently large sample size, remaining individual differences will likely average out).
Example in R
To investigate such causal relationships in statistics, we often use statistical models. One way to do this in R is to use linear regression models to examine the influence of one or more independent variables on a dependent variable.
Here is an example of how you can calculate a simple linear regression in R:
# Simulated data for caffeine consumption and concentration
set.seed(123)
Koffein <- c(0, 1, 0, 1, 0, 1, 0, 1)
Konzentration <- c(50, 65, 45, 70, 55, 75, 50, 80)

# Data as a data frame
data <- data.frame(Koffein, Konzentration)

# Linear regression
modell <- lm(Konzentration ~ Koffein, data = data)

# Summary of the model
summary(modell)
In this example, you are investigating whether caffeine consumption (the Koffein variable) affects concentration (Konzentration). The result tells you whether the relationship is statistically significant—in other words, whether we can assume that caffeine actually influences concentration.
But what certainly hasn’t escaped your notice is that we are only addressing the first criterion here. In this context, we simply have to assume the other two. And it is an important task for statisticians to continuously question whether the assumptions fit the calculations!
And it is an important task of the statistician to continuously question the extent to which the assumptions fit the calculations!
Conclusion
Causality helps us understand why things happen. In statistics, it enables us to go beyond mere associations and investigate the causes of phenomena. Whether through experiments or statistical models—when we understand causality correctly, we can make well-informed decisions and better understand the world around us.